Databricks
 Databricks
 consulting services
Enterprises move to Databricks for large data volumes, many pipelines and AI that has to run in production. We’re strongest where a legacy ETL estate has to move there without the reporting layer going dark. Teams on Fabric can add Databricks alongside it, and what they’ve built carries over.





Start where you are
Your starting point shapes the platform
Most Databricks engagements begin with one of these three.
- Migrating
We have a legacy ETL estate that has to move without the reporting going dark.
The tooling converts the repeatable logic; engineers convert the special cases by hand. Every converted pipeline ships with tests your team can run.
Start with: a migration assessment of the current estate.
- Building
We are building a lakehouse from the ground up.
Lakehouse layout and the access model are hard to change later, so we settle them first.
Start with: the lakehouse layout, workspace design and access model.
- AI on your data
We want AI answering questions from the platform we already have.
Connecting a model to a lakehouse is the easy part; answers the business can check also need grounding, access control and clean data upstream.
Start with: the data quality and lineage upstream of the model.
Databricks delivery
Legacy ETL into Databricks, with a test for every conversion
A major national retailer had committed to Databricks, with hundreds of legacy ETL workflows standing between the decision and the outcome. We built an AI-assisted migration tool on Claude that converts legacy ETL into PySpark pipelines on Databricks, with unit tests and infrastructure as code generated alongside every conversion.
- Databricks
- Claude
- PySpark
 Claude
 PySpark
- In scope: 31 workflows and 36 mappings
- In scope: 60 orchestration jobs and 50 shell scripts
- Converted into PySpark pipelines by a tool built on Claude
- Unit tests generated with every conversion
- Infrastructure as code through Terraform and GitHub Actions, generated alongside
- Output validated by senior engineers against known behavior
Start with a look at what you already have
A migration assessment sorts what automation can carry from what needs senior hands, with reporting protected throughout.
Talk to us about scopeDatabricks services
Move the estate, keep the platform running
Architecture and engineering across the platform lifecycle, from legacy estates to new data and AI workloads.
ETL migration
Legacy ETL migration
AI-assisted conversion of legacy ETL into Databricks pipelines, with generated tests and infrastructure as code for every conversion
Automated conversion of transformation logic, orchestration and deployment configs
Generated unit tests and infrastructure as code with every converted pipeline
Parallel run against the legacy estate until output parity is validated
- Estate assessment
- AI-assisted conversion
- Generated tests
- Parallel validation
Architecture
Architecture and platform fit
A platform recommendation scored against your estate, then one governed lakehouse for engineering, analytics and AI
Estate, licensing and workload review with a written platform recommendation
Lakehouse layout, workspace design and access model, decided once
Medallion-pattern modeling with test coverage across tiers
- Platform fit
- Platform design
- Data modeling
- Access design
Data engineering
Data engineering and pipelines
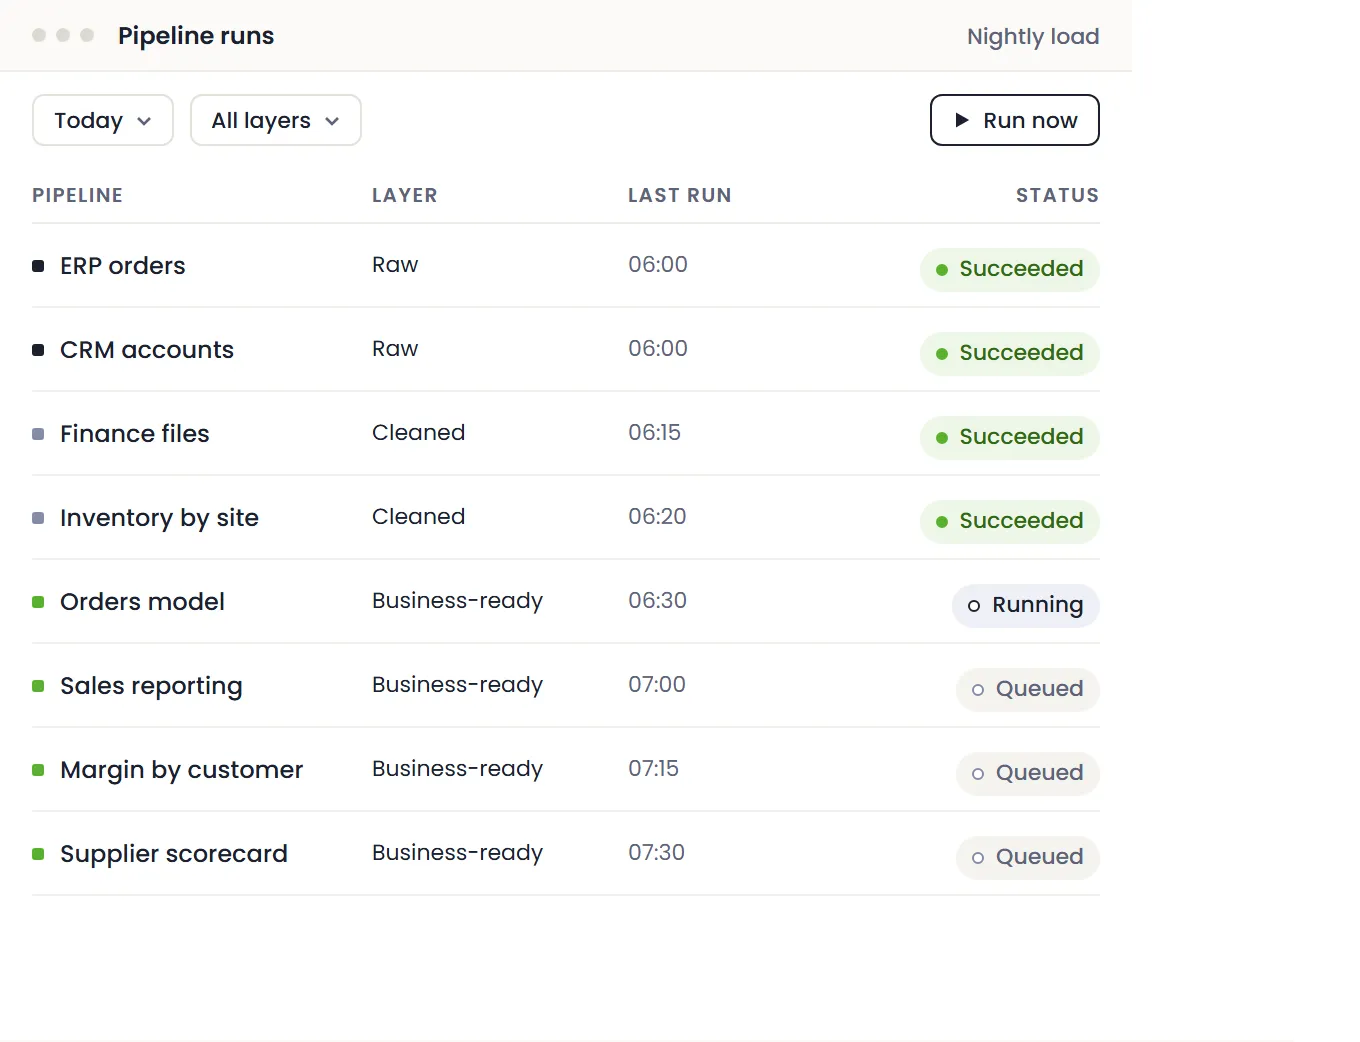
Ingestion, transformation and orchestration built to run unattended, for batch and streaming workloads
Source extraction with incremental loading and change data capture
Orchestration with scheduling, monitoring and automated error handling
Streaming and event-driven pipelines alongside batch
- Data integration
- Orchestration
- Monitoring
- Streaming
AI on your data
AI on lakehouse data
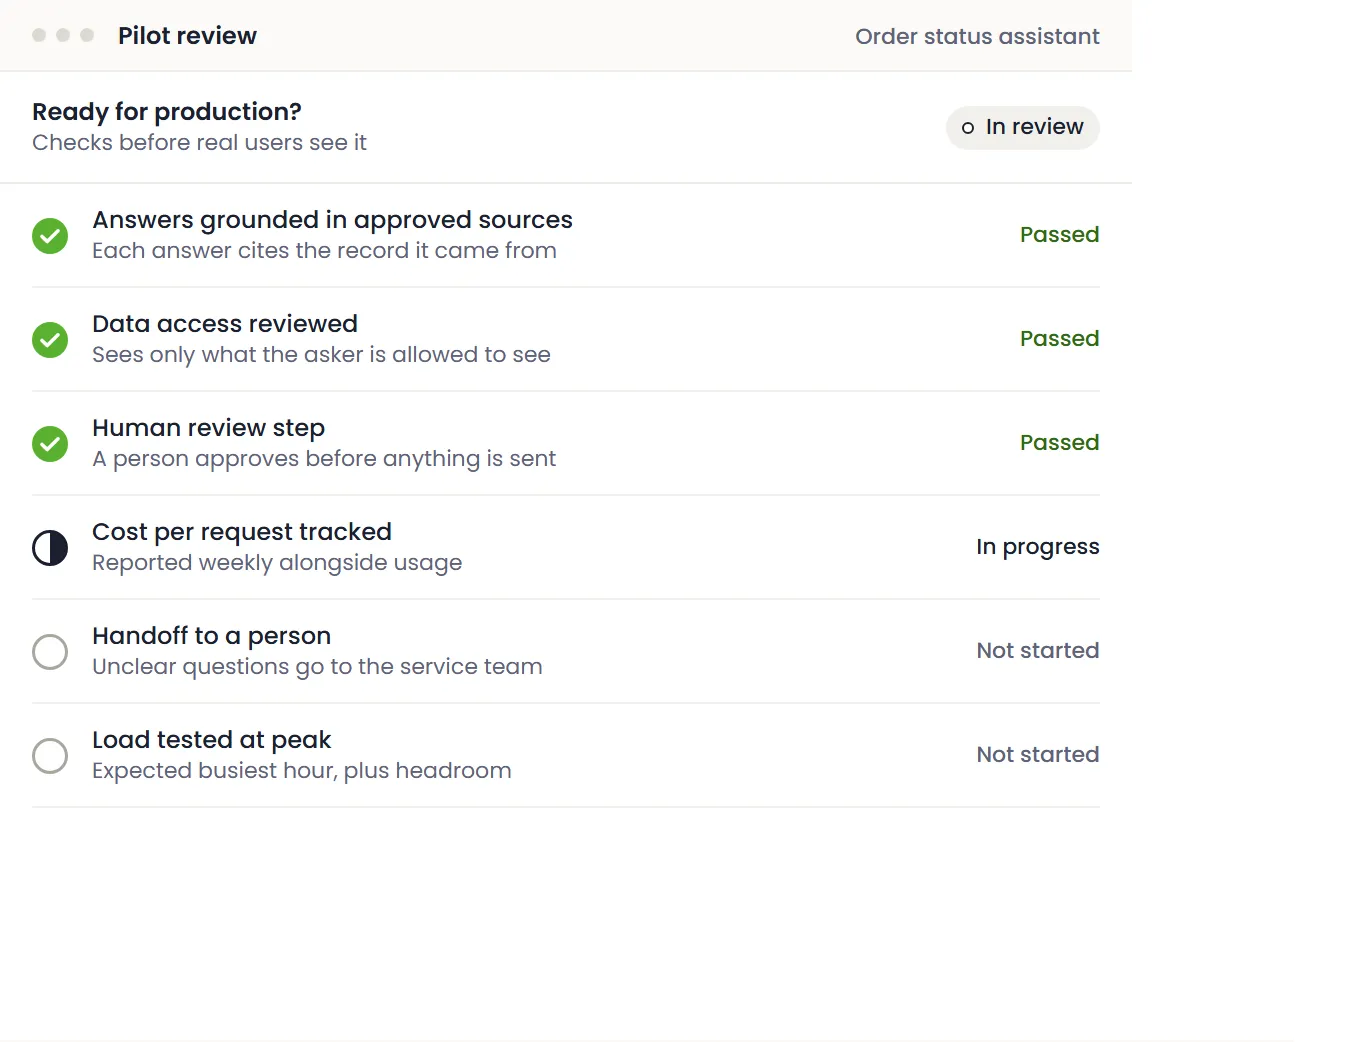
Language models grounded in your schema and your access rules, so the answers they give can be checked
Schema-grounded SQL generation, with the query shown alongside every answer
Governed access, so a model sees only what the person asking is allowed to see
Model routing and cost measured before AI workloads reach the lakehouse at scale
- AI on your data
- Unity Catalog
- Data quality
- AI cost
Governance
Governance and access control
Lineage, classification and permissions set up with the build, not retrofitted after an audit
Role-based access aligned to data classification
Lineage and audit visibility across the estate
Quality rules enforced in the pipeline, not the wiki
- Access design
- Lineage
- Data classification
- Quality rules
Databricks partnership
Databricks Bronze partner
Smart Data is a Databricks consulting partner at the Bronze tier, and has delivered enterprise software since 2006.
 Databricks
Output your team can verify
Converted pipelines ship with generated tests and infrastructure as code, so your platform team can check the work.
More than one platform
We build on Databricks, Fabric and Snowflake, so the recommendation follows your estate.
Our process
How our Databricks engagements work
The phases adjust to where your estate is starting from.
 Phase 01
Migration assessment
Decision point · Written plan
We inventory the estate: transformation logic, orchestration, deployment configs, sources and the reporting that depends on them. Then we sort what automated conversion can carry, what needs senior hands and what should be retired rather than moved. If Fabric or a simpler path fits better, the plan says so.
Deliverable: a phased plan and a written platform recommendation.
 Phase 02Sized in the assessment
Convert, test and parallel run
Working solution · Measurable outcome
We convert the estate into PySpark pipelines on Databricks, with unit tests and infrastructure as code generated alongside each one. Senior engineers take what the tooling cannot. Old and new run in parallel until output parity is validated.
Deliverable: converted pipelines with their tests, and output parity validated against the legacy estate.
 Phase 03Ongoing
Operate and extend
Expand what works · Embed into operations
After cutover there are usually more domains to bring on, streaming to add and AI use cases waiting on governed data. We can stay on through managed services with P1 to P4 response times, or enable your team to run and extend it independently.
Deliverable: source control, deployment pipelines and documentation your engineers can maintain.
Migration in practice
A migration you can work through
A defined path from understanding the estate to a platform your team can run.
Where you are
- Transformation logic
- Orchestration jobs
- Deployment configs
- Source systems
- The reporting that depends on them
- 01Understand the estate
- 02Convert and test
- 03Validate in parallel
- 04Transition and support
Reporting stays up throughout, and the legacy estate is retired last.
Where you land
- PySpark pipelines
- Generated unit tests
- Infrastructure as code
- Lakehouse
- Batch and streaming
Industries
Industries we work in
Healthcare
Patient, pharmacy and clinical data systems held to HIPAA, including where AI is allowed to touch them.
- Medicaid programs
- Pharmacy services
- Clinical documentation
Clients include
See healthcare work

Manufacturing and industrial
ERP, shop-floor and supplier data on one platform, so plant reporting and finance reporting reconcile.
- SAP and ERP reporting
- Shop-floor integration
- Supplier portals
Clients include
See manufacturing work
Retail and distribution
Order, inventory, credit and customer data connected across portals, branches and the platforms behind them.
- Vendor and customer portals
- Order and credit systems
- Data platforms
Clients include
See retail and distribution work
Financial services
Bank data platforms, reporting that holds up to an audit and managed support for the financial systems the business runs on.
- Bank data platforms
- Managed ERP support
- Legacy migration
Clients include
See financial services work
Insurance
Claims, member and policy systems for health plans and insurers.
- Health plans
- Claims data
- Member apps
Clients include
See insurance work
A few practical questions
Work through the decisions
Common questions about Databricks consulting, legacy ETL migration, lakehouse architecture and what happens after cutover.
Ask us about your situationShould we be on Fabric or Databricks?
If you run mostly on Microsoft, you can usually start on Fabric and bring Databricks in when your data work outgrows it. The two work together, so what you’ve built carries over. Databricks leads when the work is heavy machine learning, GenAI, streaming or complex transformation. We build on both, so the answer follows your estate.
Snowflake or Databricks?
Databricks is lakehouse-first and suits engineering-heavy work: streaming, large-scale transformation and machine learning. Snowflake is warehouse-first, with governed sharing and simple operations. Many enterprises run both, and plenty of mid-market teams need neither yet.
Are you a Databricks partner?
Yes. Smart Data is a Databricks consulting partner at the Bronze tier. We also build on Fabric and Snowflake, so the platform recommendation follows your estate rather than the partnership.
How long does a legacy ETL migration to Databricks take?
It depends on the size and variety of the estate, and the migration assessment sizes it before anything moves. The tooling converts the repeatable logic; engineers convert the special cases by hand and validate the output. Aim for one Gold use case in 90 days, not the whole estate.
What does your migration tooling convert?
Transformation logic, orchestration scripts and deployment configurations, into PySpark pipelines on Databricks, with unit tests and infrastructure as code generated alongside. What the tooling cannot carry goes to senior engineers. The assessment shows the split for your estate before anything moves.
Do you use AI for the conversion?
Yes. Our migration tooling is built on Claude with structured prompts, and it generates the tests and deployment automation with each converted pipeline. Senior engineers validate the output against how the legacy jobs behave.
How do you know the converted pipeline is correct?
Expected outputs are part of the inputs, so every translation is checked against a known-good result. The tooling iterates until back-to-back runs produce the same result, so the output is stable before anyone reviews it.
Will reporting go down during the migration?
It shouldn’t. Old and new pipelines run in parallel until output parity is validated, and the legacy estate is retired last.
Do you use a medallion architecture on Databricks?
Yes. Land the raw data, clean it once and publish the version people and AI models can rely on. The pattern works the same on Fabric, Databricks or Snowflake, and it keeps the evidence, so a mistake in your logic doesn’t become a permanent mistake in your history.
Can Databricks handle streaming and real-time data?
Yes. Streaming and event-driven pipelines run alongside batch on the same lakehouse, so operational and historical analysis share one copy of the data. We use incremental loading and change data capture where the source supports it.
How is governance handled on Databricks?
It’s set up alongside the build from the start. Access is designed around data classification in Unity Catalog, with lineage and audit visibility across the estate and quality rules enforced in the pipeline.
Can we put AI on our Databricks data?
Yes, with the groundwork first. The model gets your schema and your access rules, writes the query and shows it alongside the answer so it can be checked.
How do you keep Databricks costs under control?
Language model workloads can run up compute quickly, so we measure model and compute cost before AI workloads reach scale. Compute is sized to the work it actually does and monitored after go-live.
Who runs the platform after you leave?
Your team, if that is the plan, and we build toward it from the first week with source control, deployment pipelines and documentation. If you would rather we ran it, managed services covers that, with P1 to P4 response times.
Keep exploring
Other platforms and related services
We build on Fabric, Databricks and Snowflake, so we recommend the engine that fits your estate.
Platforms we build on
- Microsoft Fabric
- Databricks
- Snowflake
 Microsoft Fabric
 Snowflake
Exploring a Microsoft-centered analytics foundation?
See our Microsoft Fabric approachData engineering
Pipelines off SSIS and legacy ETL, and warehouses that reconcile.
Learn moreAI development
Language model features in your applications, and private models where data has to stay put.
Learn moreManaged services
Monitoring, fixes and enhancements after go-live, with P1 to P4 response times.
Learn more
Next step
Start with a migration assessment
Here is what happens after you reach out.
A short call about your data estate
What is in the estate today, what has to move and what is driving the timing.
An engineer looks at what’s running
Scope comes from your systems as they are, before anything is priced.
You get a written proposal
Covering scope, team, approach and price.