Skip to content
Smart Data
Streaks of blue and green light across a dark background

AI

Governed AI on your own data

A language model pointed at a lakehouse with no structure around it runs up a large bill and gives answers nobody can check. We design and build AI that runs on your own data, inside your access rules, on models sized to the job, with the query behind every answer in plain view.

Sound familiar?

Where AI on enterprise data stalls

Most companies already use AI somewhere. The trouble starts when it meets the data the business runs on.

  • Pilots

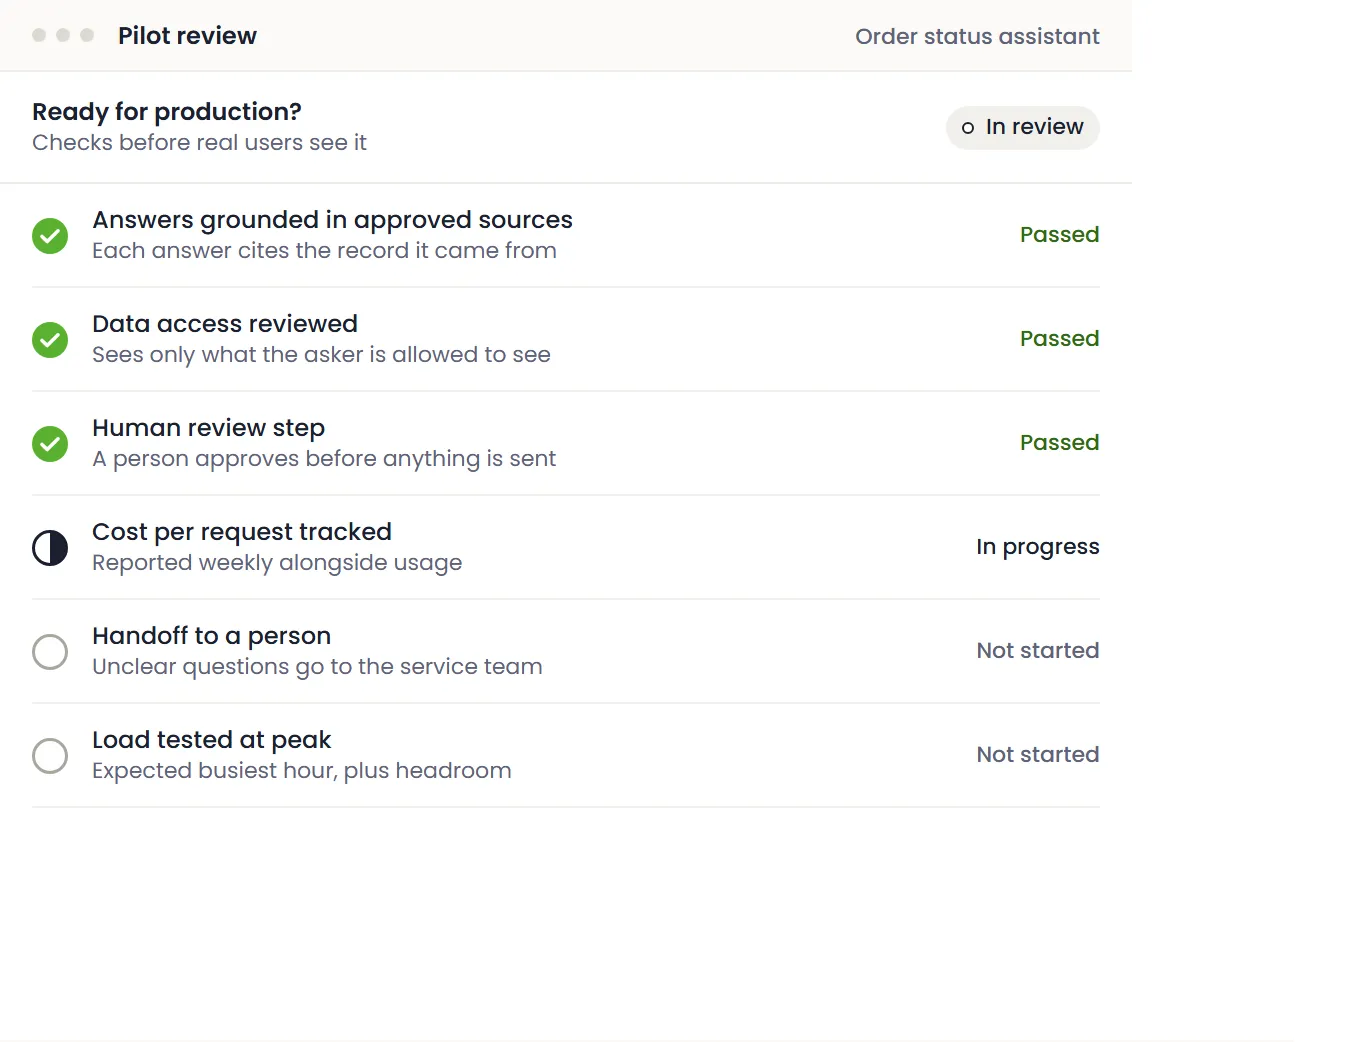
    The pilot impressed in a demo and never reached production

    It ran on sample data with nobody’s access rules applied. Production has both. We start from the governed data the pilot skipped.

    Start with: the data the use case depends on.

  • Answers

    The assistant answers confidently, and sometimes wrongly

    A model guessing at table names and business definitions will guess wrong. Give it the schema and the definitions, show the query behind every answer, and a wrong number gets caught before anyone acts on it.

    Start with: one governed domain and its definitions.

  • Cost

    Usage keeps climbing, and so does the bill

    Sending every question to the largest hosted model is the most expensive way to answer it. Routing work to right-sized and private models turns AI spend back into a number you can plan.

    Start with: what is used today, by whom and at what cost.

How we approach it

What we design and build

Context and semantics come before agents. These are the pieces of a governed AI system on your own data, usually built in this order.

Schema-grounded answersQuestions answered in SQL anyone can check

Schema-grounded SQL with checkable answers

The model gets your schema, your business definitions and the question, and writes the SQL that answers it. The system around the model is built to keep it from making answers up: queries are validated against the schema, run with the asker’s permissions and returned with the answer, so anyone can see how the number was reached.

  • The generated query shown with every answer
  • A router sends each question to a translator that knows that part of the business, working from the semantic model and the schema
  • Queries validated against the schema before they run
  • Business definitions kept in a semantic layer, not buried in prompts
  • Microsoft Fabric
  • Databricks
  • Snowflake
Governed accessThe model sees only what the asker may see

Governed access and audit

Access rules, sensitivity labels and audit trails come from the data platform, so the model sees only what the person asking is allowed to see, and every question and answer can be traced afterwards.

  • Row- and column-level security enforced at query time
  • Every question, query and answer logged for audit
  • Sensitive fields classified before any model can reach them
  • Microsoft Purview
  • Unity Catalog
  • Microsoft Entra ID
Data governance and quality
Private and local modelsModels that run where your data is allowed to go

Private and local models

For high-volume or regulated workloads, a small private model can cost less to run and be easier to govern than a public API. We design for hosted, private-cloud and on-premises models, chosen by what the data allows and what the task needs, and keep regulated data inside your environment.

  • Open-weight models run in your cloud tenant or on your own hardware
  • Hosted frontier models used where the task needs them and the data permits
  • One interface for your people, whichever model answers
  • Ollama
  • Azure
  • AWS
Model routing and AI costEach task on the smallest model that does it well

Model routing and AI cost control

Not every question needs the largest model. We route each task to the smallest model that answers it well, cache what repeats and measure cost and accuracy per answer before a workload scales, so you know what the AI bill will be before it arrives.

  • Routing rules that match each task to a right-sized model
  • Cost per answer tracked alongside accuracy
  • Spend visible by team and use case before the invoice arrives
OrchestrationGrounded answers that drive multi-step work

AI orchestration

Once answers are grounded and governed, they can drive work: multi-step workflows that look something up, check it against policy and hand it to the next system or person. A person approves anything that changes a system of record.

  • Workflows built from grounded, permission-aware steps
  • Human approval before any write to a system of record
  • Every step logged, so a result can be traced back to its sources

Our point of view

Don’t just point a language model at your lakehouse

Treat AI spend the way you treat cloud spend: track the cost of each answer, where its data came from and whether it was right. That’s how AI on your own data stays governed, and its cost stays planned.

  • Context before agents

    Schema, definitions and a semantic layer come first.

  • Cost is a design input

    Model choice, routing and caching are decided at design time, with a cost per answer attached.

  • Your data stays yours

    Private and local models where the data requires them, and hosted models only where it allows.

  • Every answer can be checked

    The query, the sources and the model behind each answer are visible to the person who asked.

AI Enablement GuideA guide from Smart Data

How this connects to AI

Not sure your data is ready for AI?

Not sure your data is ready? The AI Enablement Guide covers what the AI programs that reach production do differently, and how to assess your own readiness.

How an engagement runs

One governed use case first, then the next

Aim for one Gold use case in 90 days, not a full data warehouse rebuild. Each phase ends with something you can use and a decision about the next.

  1. 01

    01Workshop

    One to two weeks on your data, systems and use cases. Where AI is already in use, what it costs, what data it touches and which use case has the data to support it.

    Deliverable

    A readiness scorecard, a 90-day roadmap of use cases ranked by impact and data readiness, a recommended architecture and a scope for the first build.

  2. 02

    02Prove it on one domain

    A context layer on one governed data domain, then schema-grounded answers on top of it, on your real data and in your environment.

    Deliverable

    Working software on your data, with accuracy and cost per answer measured.

  3. 03

    03Scale and run

    More domains, routing and private models where they pay off, and the governance to keep it all auditable. We run it with you or hand it to your team.

    Deliverable

    A routing and hosting design, a governance policy and a support plan.

Scoped projects, staff augmentation or managed support after launch.See how we deliver

Industries

Industries we work in

A few practical questions

Questions about AI on your data

What data and IT leaders usually ask before AI touches production data.

Ask us about your situation
What is schema-grounded SQL generation?

The model is given your database schema, your business definitions and the question, and writes the SQL that answers it. The query runs with the asker’s permissions and comes back with the result, so the answer can be checked. Riel St. Amand, our AI Solutions Advocate, presented the method at Dayton AI Day in August 2026 in a talk titled “Beyond RAG and Fine-Tuning: Schema-Grounded SQL Generation for Verifiable Enterprise Analytics.”

Why not just connect a chatbot to our data?

Because it will answer whether or not it knows. Without the schema, the definitions and the access rules, a model guesses at what a column means and who may see it, and the cost grows with every question. That’s the work we do before anyone in the business uses it.

Do we need our own models?

Not always. Hosted models are the right call for many tasks. Private or local models make sense where the data is regulated, where volume makes per-call pricing expensive or where the model should stay in your environment. We design for the mix your data and budget support.

Does our data need to be perfect before we start?

No. The assessment shows which use cases your data supports today and what has to change before the rest become viable. The first build usually starts on the domain that is already in the best shape.

What happens to our data when AI touches it?

We only use AI tools with training on your data turned off. If your contract restricts AI or requires stricter handling, such as zero data retention, your contract wins. We use US-based providers.

Which platforms does this run on?

Microsoft Fabric, Databricks and Snowflake, and the governance tools that come with them. The semantic layer and access rules live in the platform you already run, so AI inherits them.

Next step

Which question should your data answer first?

Tell us the question, the data behind it and how AI is used today. Here is what happens after you reach out.

  1. A short call about the use case and its data

    What you want answered, where the data lives and who is allowed to see it.

  2. An engineer looks at what’s running

    Scope comes from your systems as they are, before anything is priced.

  3. You get a written proposal

    Covering scope, team, approach and price.

info@smartdata.net(937) 886-9166

Tell us what you are working on

We use your details only to reply.

Your privacy choices

Choose what this browser shares with us. The site works the same either way. Privacy policy